Status: internal measurement against a simulator, not peer reviewed, and not validated against a molded part — no press trial has been run. "Error" below means disagreement between two grid pitches of the same solver. Tier: a negative result, and a mechanism — the geometric refinement criterion everyone reaches for first does not work, and the thing that does work can only be computed after you have already solved once.
1. Summary
Given a coarse-pitch fill solution and its 2× refinement, where do they disagree?
Local wall thickness predicts essentially nothing — out-of-part Spearman 0.10. This is the negative result, and it is the one that costs something, because "thin walls need cells" is the intuition every adaptive-meshing scheme starts from.
The coarse solution's own value predicts it almost entirely. A learned model over the coarse fields reaches 0.93, and the one-line rule "the colder the coarse cell, the more wrong it is" reaches 0.87 on its own.
The consequence is structural: a refinement criterion for this problem has to be computed after a coarse pass. It cannot be read off the geometry before solving, which is precisely what an a priori meshing strategy needs it to be.
2. Method
30 parts, each with a coarse label and a 2× label — 220,447 cavity cells. Five-fold cross-validation grouped by part, so every number quoted is out-of-part: the model never sees a cell from a part it is scored on.
The target is per-cell |error| between the two pitches.
The bars were set before the fit: a candidate had to beat the thickness rule by +0.10 to count as a finding, and reach ≥ 0.50 Spearman and ≥ 0.30 worst-decile IoU to count as usable.
3. Results
| predictor | out-of-part Spearman on per-cell |error| | worst-decile IoU |
|---|---|---|
| local wall thickness alone | 0.10 | 0.07 |
| all geometry + process (thickness in cells and mm, gate distance, a distance-rank prior, spacing, rate, fill time) | 0.49 | 0.13 |
the one-line rule −m_ch(coarse) | 0.87 | 0.47 |
| learned model over the coarse solution's own fields | 0.93 | 0.47 |
The geometric feature set — everything available before solving, not just thickness — fails the usable bar on both of its halves. On ranking it reaches 0.49 against 0.50, a miss of 0.007 that should be stated plainly rather than rounded into a pass. On localization it is not close: worst-decile IoU 0.13 against a bar of 0.30. Geometry and process carry some ranking signal; they do not find the worst cells.
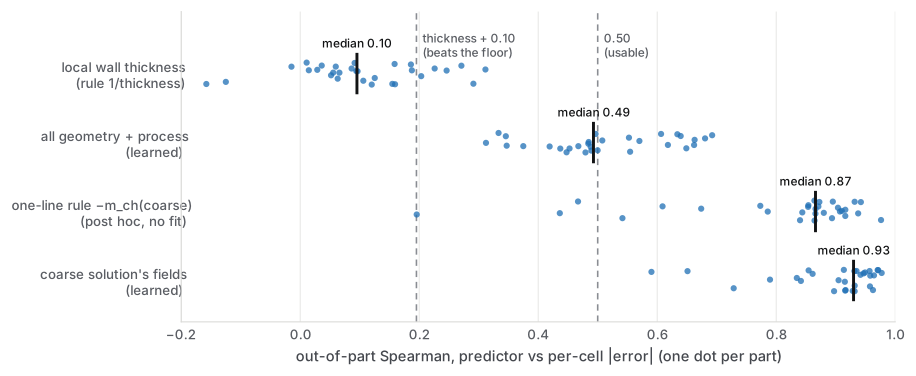
Per-part skill of each predictor. One dot per part, scored out-of-part; black ticks are medians. The geometry-and-process model straddles the 0.50 line part by part (the Spearman half of the usable bar; it fails the IoU half, 0.13 against 0.30, clearly); both predictors that read the coarse solution sit near the top on most parts. The one-line rule was found after the fit and is not a bar; its per-part values are recomputed here from the per-cell table and reproduce the recorded median. Source: runs/20260913-stage0-discrepancy/cv_results.json and build/stage0/cells.npz (rheia).
The one-line rule also localizes the worst decile at IoU 0.47, which is what you would actually gate refinement on — more than three times what geometry and process manage.
The error has a sign. The coarse label is colder than its refinement on 98 % of cells — median error −0.15 in margin units, top decile 0.5. This is the same direction reported in the pitch-convergence note: refinement moves the field warmer. Here it is resolved to the cell.
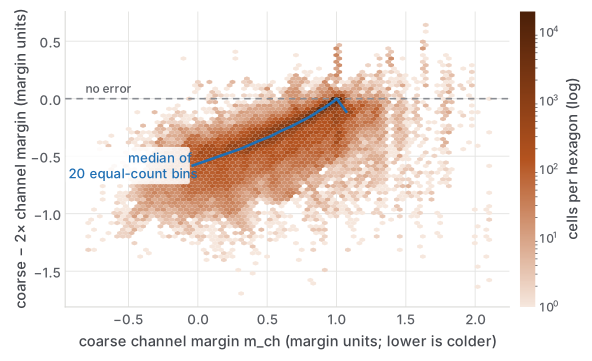
Coarse-minus-2× error against the coarse value, every cell. Almost all the mass is below zero, so the coarse label is colder, and the error grows as the coarse cell gets colder: the rule −m_ch(coarse) read off the chart. The line is the median in 20 equal-count bins of coarse margin. Source: build/stage0/cells.npz (rheia), the per-cell table the fits were run on.
4. Why the coarse solution knows where it is wrong
The rule is not a coincidence of this corpus. A coarse cell reads cold because the front spent too long in contact with too much cavity wall per cell — the same discretization artifact that makes the field converge badly at short fill times. The artifact writes its own signature into the value: cells that are wrong are cold because they are wrong.
That is why the coarse solution outperforms the geometry. The geometry encodes where cells are small. The coarse solution encodes where the numerics actually went astray, which is a different and much smaller set.
5. What we did about it
A proposal was live at the time to learn a "cell-size field" as an operator — predict the required pitch from geometry, mesh once, solve once. This result killed it. The information needed to place cells is not in the geometry; it is in a solution you do not have yet.
What survives is a cheaper design: solve coarse, apply −m_ch(coarse), refine
the cold decile. That is a solve-then-refine loop rather than an a priori mesh,
and it costs an extra pass.
6. What this does not establish
−m_ch(coarse)is a ranking, not a calibration. It says which cells are most wrong, not by how much. Nothing here converts it into an error bar.- The Spearman half of the usable call is narrow; the IoU half is not. A different feature set or corpus could lift the geometric model's 0.49 over 0.50. Its 0.13 localization is a long way from 0.30, and the finding that survives either way is the gap — 0.49 against 0.93 on ranking, 0.13 against 0.47 on localization.
- 30 parts, one material, one press slate (VICTREX 450G, Sodick LP20EH3 defaults).
- 2× is not convergence, so "error" here is a lower bound on the real discretization error.
- Whether refining on this criterion actually recovers the field is a separate question, and the answer in this series is no — see the nested-refinement work, which is not yet published.
- No molded part has been measured.
7. Records
Pre-registered: docs/2026-09-13-stage0-discrepancy-field-preregistration.md
(bars in §3 were fixed there before the fit). Run data:
runs/20260913-stage0-discrepancy/. FutureMold engine at commit fb1023bf.
Colophon — authorship and AI assistance
Author (responsible natural person): Anderson Brunsvold, Future Micro Mold.
The corpus, the fits and the cross-validation were scripted and run by an AI agent (Claude, Anthropic) in the FutureMold repository under the author's direction; the prose is AI-drafted and human-reviewed. The bars were written into the pre-registration before the models were fit, which is the only reason the geometric model's result is reported as a failure rather than re-described as a success.
No result here has been reproduced by a second implementation or a second party, and none of it has been checked against a molded part.